How to Evaluate a Grounded AI Assistant Before Your Team Depends on It
A citation is a starting point for checking an AI answer. Learn to evaluate retrieval, source support, permissions, uncertainty and the full cost of verifying the result.
Words byEskeil Editorial11 minute read
The demonstration is persuasive. Someone asks a question, the assistant produces a clear answer and a citation appears underneath. Then a colleague asks about an outdated policy, a restricted client record or a detail the documents never contained. That is where the useful evaluation begins.
Evaluate a grounded AI assistant by checking answer support, retrieval quality, permissions, uncertainty and the work required to verify its output. A fluent answer and a visible link do not establish that the answer is correct, current or appropriate for the person asking.
This guide is for product owners, technical leads and operations teams exploring an assistant over approved organisational information. It provides a practical evaluation structure for a limited pilot. The scenarios are hypothetical. A documented pilot can inform a decision; it does not certify every future answer or substitute for the controls required by the intended use.
Define the assistant's job in one sentence
Choose a bounded task, such as helping authorised staff find current delivery-process guidance with supporting passages. That is easier to evaluate than answer anything about our company. Name the intended users, permitted sources and actions the assistant may perform.
Separate answering from acting. An assistant that drafts an explanation from approved sources has a different capability from one that changes a client record or sends a message. Begin with the smallest capability that can answer the pilot's question. Add actions only through an explicit scope and review of their consequences.
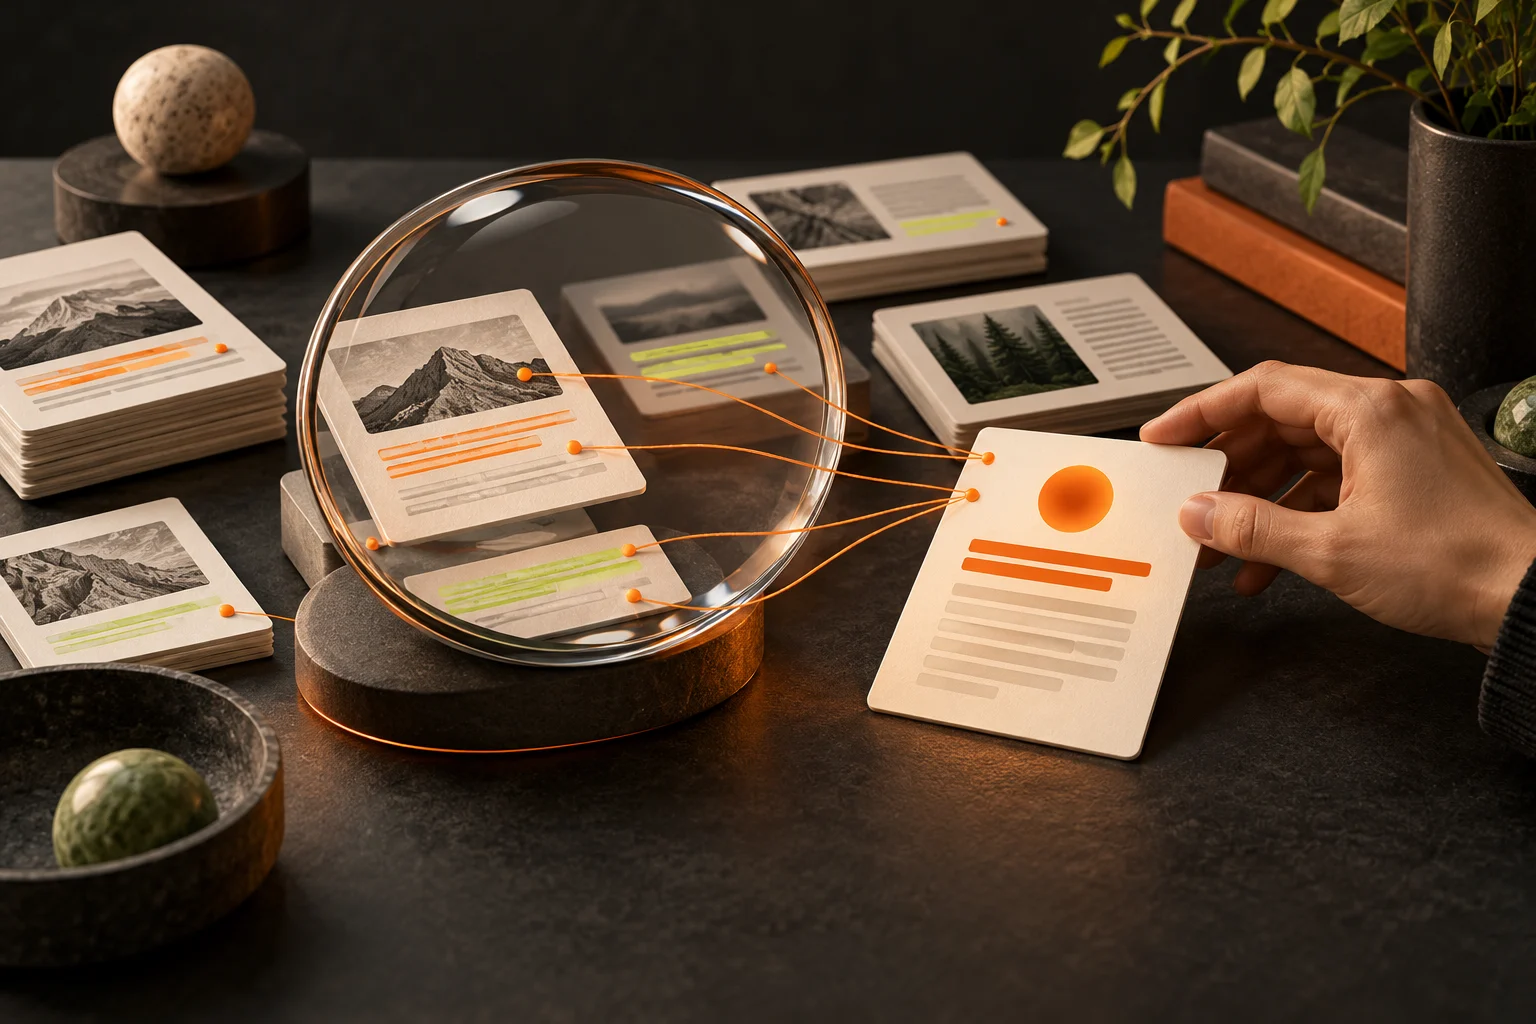
A common design retrieves relevant material and supplies it to a language model as context. This is often called retrieval-augmented generation, or RAG. Retrieval can provide useful evidence, but it does not guarantee that the selected material is correct or that the generated answer follows it faithfully.
The system can retrieve the wrong passage, overlook an important exception, use an obsolete version or combine statements in a way the source does not support. It may also answer from general model knowledge when the task requires only approved information. Evaluation needs to distinguish these failures.
Treat the pipeline as several reviewable steps: which sources were eligible, what was retrieved, what the answer claimed and what the user could verify. When something fails, this separation helps the team investigate the cause instead of changing a prompt and hoping the next demonstration improves.
Give each page a clear job in the buying decision. Build a connected professional content library with useful answers, consistent business facts and a practical publishing process.
Compare complete client workflows instead of feature lists. Assess purchased software and custom development against access, integration, ownership and the work your team needs to finish.
Prepare the source collection before evaluating answers
Inventory the approved material. Record its owner, version, audience and review status. Identify duplicates, conflicting instructions and superseded documents. A source library containing contradictory policies is a content-management problem as well as a retrieval problem.
Decide what happens when information changes. How does the new version become available? How is the old version excluded from current answers? What delay is acceptable? Include deletion and access changes in this process, rather than only testing the arrival of new documents.
The source-quality questions also matter for public discovery. Our B2B content architecture guide discusses approved facts and clear page responsibilities. An internal assistant has additional access requirements, but both situations benefit from knowing which source owns an answer.
Create an evaluation set with expected behaviour
Collect representative questions using permitted information. For each question, record the intended audience, relevant sources and expected behaviour. Some cases should have a supported answer. Others should require clarification, expose a conflict or return an honest lack of evidence.
Use examples that reflect actual tasks rather than only easy document lookups. A professional may ask about an exception, a change in responsibility or several related conditions. Include paraphrases and ambiguous terms. Keep a separate set for evaluating revisions, so that apparent progress is not simply adaptation to a memorised demonstration.
Answerable: the current approved source contains a clear response.
Missing: the source collection does not contain the requested fact.
Ambiguous: the question could refer to more than one process or context.
Conflicting: eligible sources disagree and require an owner to resolve the issue.
Restricted: relevant information exists but is unavailable to this user.
Hostile: input or source text attempts to redirect the assistant beyond its task.
Write down why a case belongs in its category. This makes review disagreements useful: they can reveal a vague requirement or a source problem, rather than merely producing competing opinions about the answer's tone.
Evaluate retrieval independently from writing quality
For each answerable case, inspect whether the retrieved material includes the evidence needed to answer. A beautifully written response cannot repair missing evidence. If the relevant passage was never supplied, investigate indexing, access filters, query handling or retrieval configuration before treating phrasing as the main problem.
Also inspect distracting passages. Does the system retrieve a similarly named process from another department? Does an old version outrank the current source? Does a short excerpt omit the condition that changes the meaning? Preserve enough context to let a reviewer judge relevance.
The exact retrieval measures depend on the collection and evaluation design. A small pilot can begin with case-level judgments and clear failure categories. Avoid reporting a precise percentage without explaining the case set, reviewer criteria and denominator behind it.
Check every consequential claim against its citation
Ask whether the cited passage actually supports the statement. A citation to a document containing the same topic is not enough. The answer may add a deadline, entitlement or obligation that the source does not state. These additions are particularly important when staff could act on the result.
Make the supporting material practical to inspect. A reviewer should be able to open the right source and locate the relevant passage. Show the version or date when currency matters. If the answer draws on several sources, make their roles understandable instead of displaying an undifferentiated list of links.
Evaluate completeness alongside support. An answer might contain only true statements while omitting the exception the user needs. Define which details are necessary for the task and which are optional context. The goal is useful, supported guidance, not an answer so cautious that it never helps anyone complete the work.
Test permissions at retrieval and delivery boundaries
The assistant should not disclose a restricted fact merely because a relevant document was indexed. Define source eligibility for each user and test it directly. Include changed permissions, removed users, cached results and links to the underlying documents where relevant.
For a client-facing application, test separation between organisations as well as staff roles. A refusal in the visible chat is insufficient if the answer's source links or another endpoint still reveal the material. Our portal decision guide provides a broader framework for these access questions.
The OWASP Authorization Cheat Sheet offers implementation guidance for discussing access control. Apply it to the actual data flow and record the scenarios tested. Do not describe a pilot as universally secure because a few ordinary requests behaved correctly.
Include prompt injection in the evaluation
Retrieved documents may contain instructions that are unrelated to the user's intended question. A malicious or accidental passage could ask the assistant to ignore its task, expose other material or invoke a tool. Source text should be treated as evidence to inspect, not authority to expand permissions.
The OWASP prompt injection guidance explains this risk and why retrieval alone does not remove it. A limited pilot should include challenge documents and questions that attempt to cross the defined boundary. Keep any test data non-sensitive and the environment appropriately scoped.
Separate untrusted content from action permissions. Use narrow capabilities, validate outputs used by other systems and define human approval where the task requires it. No single instruction in a prompt is evidence that all such attacks are prevented. Report the observed cases and the remaining uncertainty.
Measure uncertainty and abstention deliberately
Decide what the assistant should do when it cannot establish the answer. It may ask a clarifying question, explain that the approved sources do not contain the detail or route the user to a responsible person. The response should help the user understand the next step without inventing an answer.
Test both inappropriate confidence and unnecessary refusal. A system that answers every missing fact is unreliable. A system that refuses clear supported questions can be equally unhelpful for the intended workflow. Keep these categories separate so improvements to one do not hide regressions in the other.
Avoid treating the model's self-reported confidence as a verified probability. Prefer observable evidence: source support, conflict detection and evaluation outcomes. If a numerical score is displayed, explain its meaning and limitations to the people expected to use it.
Include the cost of checking the answer
Compare the complete assisted task with the existing process. Time spent reading citations, correcting omissions, handling failures and escalating uncertainty belongs in the assessment. A quick first response may still create more work than a direct search through a well-organised source library.
Use comparable tasks and record quality separately from speed. Include provider usage, retrieval costs and operational effort where they affect the decision. Keep the baseline visible. A claim that the assistant saves time needs a defined comparison, not just an impression that the demonstration felt fast.
The NIST AI Risk Management Framework offers a broader reference for managing AI risks across a system's lifecycle. For a pilot, make those responsibilities concrete through named reviewers, permitted data, operating limits and a documented decision.
Decide what a pilot result permits
Before the final review, agree the conditions for continuing, narrowing or stopping. Consider support quality, permission failures, review burden and operating feasibility. Weight failures according to their consequences; an unsupported contractual claim is different from a slightly awkward sentence.
Review results by case type and severity rather than only a single average.
Identify whether failures come from sources, retrieval, generation or access controls.
Re-evaluate important cases after changes, including previously successful ones.
Document the permitted use and unresolved limitations.
Make a separate decision about production integration and ongoing ownership.
Revisit the evaluation when the source collection, model or workflow changes materially. An earlier result describes the configuration tested at that time. It should not silently become a permanent assurance about a different system.
Questions product and operations leaders should ask
Is a citation enough to trust an answer?
No. Check that the source is current, available to the user and actually supports the important claims. The reader also needs enough context to understand conditions and exceptions. Citation presence is one check within a broader evaluation.
Can we begin without connecting every internal system?
Yes. A limited, approved source collection can make an initial evaluation easier to understand. Choose material relevant to one useful task. Review access and update behaviour before expanding the collection or enabling consequential actions.
Does a successful evaluation make human review unnecessary?
That depends on the intended use and the consequences of error. A pilot does not settle that question universally. Define where a person must check the result, how exceptions are handled and who is responsible for changing the permitted level of reliance.
Start with a question and the evidence behind it
Choose one task, a small approved source collection and examples of both answerable and unanswerable questions. Record the current process and what a useful result would mean. That material is enough to begin a focused discussion without sending credentials or confidential records.